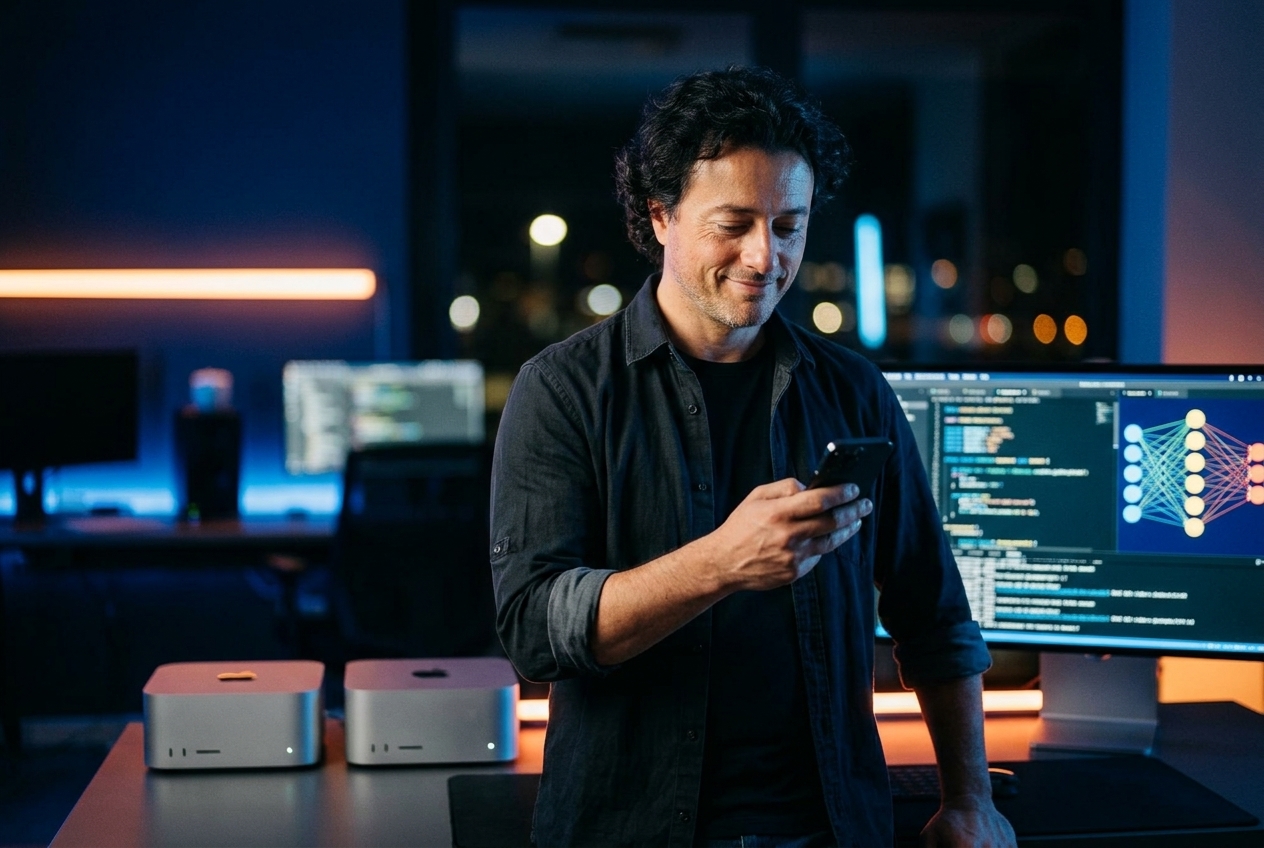
Muse Spark Open: Meta and Apple’s Unlikely Alliance Just Put an 816B-Parameter AI on Your Desktop
October 16, 2026 — by Vito Ruocco
For years, the story of artificial intelligence has been a story of scale and centralization: bigger models, bigger data centers, bigger electricity bills, and bigger monthly API invoices. The frontier of AI lived in the cloud, behind locked doors, in the data halls of a handful of companies. If you wanted the smartest model in the world to write your code, edit your videos, or run your business, you rented it by the token and prayed the provider didn’t change the pricing page overnight.
On October 15, 2026, that story changed overnight — and the two companies that changed it are the last two you would expect to be standing on the same stage. Apple and Meta, rivals who have spent the better part of a decade sniping at each other over privacy, advertising, and the future of computing, have quietly teamed up to release Muse Spark Open: an 816-billion-parameter, natively multimodal, open-weight foundation model that Meta calls “the most capable US open-weight model to date” — and the first frontier-class model in its tier designed to run entirely on your own desktop hardware, specifically on Apple’s M5 Ultra Mac Studio.
This is not a research teaser or a slideware announcement. The weights are live on Hugging Face today. The model is already available through seven major inference platforms. And Meta has published end-to-end demonstrations of the model doing real, messy, professional work on-device: shipping actual code changes to an open-source iOS app, and driving DaVinci Resolve — the professional video editing suite — frame by frame, entirely on a pair of Mac Studios sitting on a desk.
It is, in every sense, a landmark week for AI. Here is everything you need to know about the Muse Spark Open release, why Apple and Meta buried the hatchet, what the benchmarks actually say, and the other stories that defined the technology world this week.
Two Giants, One Model: The Apple–Meta Alliance Nobody Saw Coming
To understand why this announcement matters, you need to understand the rivalry it upends. Mark Zuckerberg has publicly called Apple one of Meta’s “biggest competitors.” Apple’s App Tracking Transparency update in 2021 — which let iPhone users block ad tracking by default — cost Meta an estimated $10 billion in annual advertising revenue and triggered years of bitter public sparring. Meta has poured money into AR glasses and the metaverse partly to escape Apple’s iOS grip; Apple has built its own AI stack, with on-device models and the Private Cloud Compute architecture, positioning privacy as the fundamental difference between itself and the ad-driven giants.
And yet, there was Mark Zuckerberg on October 15, posting a video of Muse Spark Open running on the new Mac Studio, with a message that reads like it came from an alternate timeline: “Muse Spark Open — weights releasing today — runs great on new Mac Studios thanks to work with John Ternus and Apple.”
John Ternus is Apple’s Senior Vice President of Hardware Technologies — the executive responsible for the M-series chips. The collaboration, first reported by CNBC and confirmed by both companies, is the most concrete sign yet that Apple has decided the way to win the “personal AI” era is not to out-build Meta in foundation models, but to make Apple silicon the best place in the world to run them.
The logic is mutually beneficial. Meta gets a flagship hardware partner that legitimizes its open-weight strategy and gives it a beachhead in the premium desktop market — the exact market where its models have historically been weakest, since most users interact with Meta AI through WhatsApp, Instagram, and Facebook. Apple gets a legitimate “killer app” for its most extreme pro hardware: a frontier-scale model that runs locally, privately, with zero cloud dependency, on machines Apple already sells (or is about to sell). It is the classic “frenemies” playbook — and it has produced the most interesting hardware-software AI announcement of the year.
The Spec Sheet: 816B Parameters, 42B Active, One Million Tokens of Context
Let’s talk about what Muse Spark Open actually is, because the numbers matter. The model is a sparsely-activated mixture-of-experts architecture with a staggering 816 billion total parameters, of which only 42 billion are active per token. That design choice — the same philosophy behind models like Mixtral, DeepSeek’s V3/R1 line, and Qwen’s MoE releases — is what makes it feasible to run something this large on desktop-class hardware in the first place: the model is enormous on disk, but each individual inference only activates a small, specialized subset of its expertise.
The headline features:
- 816B total parameters (42B active) — one of the largest open-weight models ever released by a US lab.
- 1 million token context window — enough to ingest entire codebases, book-length documents, or hours of video transcripts in a single pass.
- Natively multimodal — the model accepts and reasons over text, images, and video frames without funneling everything through a separate vision encoder.
- Built for coding and agentic work — Meta says it “excels at long-horizon tasks, complex software engineering, and multi-step reasoning.”
- On-device first — optimized for Apple’s MLX framework and the M5 Ultra’s unified memory architecture, with official support for SGLang, vLLM, TensorRT-LLM, Hugging Face Transformers, llama.cpp, and Unsloth on AMD, Apple, Intel, and NVIDIA silicon.
Meta’s benchmark claims are aggressive. According to the evaluation results released with the model, Muse Spark Open outperforms two of China’s most prominent frontier open-weight models — GLM 5.3 (Zhipu AI) and Kimi K3 (Moonshot AI) — on agentic tasks and visual reasoning benchmarks. The company is careful to frame the comparison as “the most capable US open-weight model to date,” a phrasing that implicitly concedes the Chinese labs have been winning the open-source race for the past year and a half — and that Meta intends to take the crown back.
Meta also highlights performance engineering work that goes beyond the model itself: custom, auto-tunable “Helion” GPU kernels baked into SGLang deliver 1.03–3.95× kernel-level speedups on NVIDIA and AMD GPUs and a 3% end-to-end speedup on AMD’s MI350. The subtext is clear: this is not just a model release, it’s a statement that Meta intends to compete on inference economics too, not just on raw capability.
A Terabyte of Unified Memory: Why Two Mac Studios Beat a GPU Server
The most technically interesting — and, honestly, the most surprising — part of the announcement is the hardware story. Running an 816B-parameter model locally used to be a job for a rack of A100s or H100s. Meta’s answer instead involves two deskside Macs connected over Thunderbolt, running the model split across their unified memory pools.
Here’s how it works, in Meta’s own words: “Apple’s unified memory architecture lets the M5 Ultra’s integrated GPU use up to 512 GB per Mac Studio, so two machines can hold an entire model. And the chip’s 1.2 TB/s of memory bandwidth is fast enough to read the small slice each token needs. The result is two Mac Studios behave like one supercomputer with a terabyte of unified memory.”
That last sentence is the one to remember: two Mac Studios behaving like one supercomputer with a terabyte of unified memory. The M5 Ultra’s integrated GPU doesn’t have to copy data across a PCIe bus or a network fabric — the model weights live in the same physical memory the GPU reads, which is precisely why a desktop machine can serve tokens from an 816B model at usable speeds.
There are caveats, and they are substantial. The model’s practical requirement is at least 1 TB of RAM, which means you need either two 512 GB Mac Studios (the 512 GB configuration is coming — Apple has confirmed availability “late October,” though pricing remains unannounced) or four 256 GB M5 Ultra Mac Studios. Engadget crunched the numbers and came up with a chilling figure: a four-machine setup runs roughly $38,000. That is squarely out of reach for the average consumer or hobbyist developer — the “vibe coder” demographic — but for a startup or mid-size company that has been burning through six-figure annual token budgets on API calls, $38,000 of permanent, private, unlimited-inference hardware starts to look like a bargain.
In other words, the economics of Muse Spark Open are inverted from everything we’ve gotten used to. The marginal cost of the hardware is high, but the marginal cost of inference is zero. You pay once, you own it forever, and nobody is watching your prompts. For organizations with privacy constraints — healthcare, finance, legal, defense — that tradeoff is the entire point.
Real Work, Not Demos: Ice Cubes and DaVinci Resolve
AI model announcements are drowning in cherry-picked benchmarks, so it’s worth dwelling on what Meta actually showed Muse Spark Open doing. The company paired the model with Muse Code, its AI coding terminal, and ran a series of fully on-device agentic workflows:
- Shipping real code to an open-source iOS app. Meta’s team used Muse Spark Open to drive development on Ice Cubes, a popular open-source Mastodon client, working entirely through the model — applying bug fixes, adding new features, and completing a full build of the app. This is the kind of long-horizon, multi-file software engineering task that agentic models have historically struggled with, and it was done end-to-end on a local machine.
- Driving DaVinci Resolve end to end. In the most visually striking demo, the model operated the professional video editing suite directly: reviewing footage frame by frame, identifying the strongest moments, and cropping them into vertical video. That is not a toy task — it requires visual understanding, temporal reasoning, and precise tool control, all bridged by the model’s native multimodality.
The significance here is that these are not “helpful chatbot” use cases. They are professional workflows that previously required either a human editor or a cloud agent with a fat API bill and a fragile integration. Meta’s message is that the era of the desktop agent has arrived: a model that lives on your machine, knows your files, and can operate your professional software with real autonomy — and that your data never has to leave the room.
This is also the strategic answer to the obvious question — “why would Apple help Meta?” — because the demonstrations are, functionally, the best marketing Apple could buy. The M5 Ultra Mac Studio has been positioned as a niche pro device; overnight, it became the reference platform for running frontier-class open AI locally. That is the kind of “halo” use case that sells hardware to a very lucrative buyer: developers, researchers, and studios with money.
The Open-Weight Arms Race: America Strikes Back
Strip away the celebrity hardware, and Muse Spark Open is fundamentally a geopolitical product. Meta has been explicit for months about its fear that Chinese labs are winning the open-source AI war: the company has argued publicly that the United States should not allow Chinese developers to set the standard for open models — with all the influence, talent gravity, and ecosystem capture that comes with it.
The release of GLM 5.3 and Kimi K3 — both extremely capable open-weight models from Chinese labs — escalated that pressure. Muse Spark Open is Meta’s direct response: a model explicitly benchmarked against those two, explicitly designed to reclaim the “most capable open model” title for the US, and explicitly licensed to maximize adoption. The Muse Model License includes limited commercial terms that allow many developers to use the model for free, and the weights are downloadable from Hugging Face, Amazon SageMaker AI, Google Cloud Model Garden, and Microsoft Foundry — four distribution channels that span the entire US cloud oligopoly.
Inference availability is equally broad: Baseten, Fireworks AI, Groq, Modal, Nebius, OpenRouter, and Together AI all launched serving endpoints for the model on day one, meaning even developers without a $38,000 Mac cluster can start building on Muse Spark Open today. Meta is clearly playing the open-ecosystem game to win: license permissiveness, partner breadth, and developer tooling (PyTorch TorchTitan fine-tuning support, MLX adapters, quantization-ready inference engines) all point to a company that wants this to become a default choice.
Unsurprisingly, the release also comes with a heavier-than-usual safety apparatus. Meta says Muse Spark Open went through additional safety post-training specifically because open weights carry different risk profiles, and that it was evaluated against the Meta Superintelligence Scaling Framework, which covers the most severe risk categories and sets release thresholds. The detailed model card is live on Hugging Face, with a full evaluation report promised soon. Skeptics will note that “we evaluated it and it passed our own framework” is a familiar refrain in frontier AI; the counterpoint is that the safety work, at minimum, demonstrates the industry is converging on a serious formal process for open-weight releases.
Also This Week: Amazon’s Bee, Mistral’s Timestral, and Google’s Quantum Push
Muse Spark Open was the week’s biggest story, but it was far from the only one. Three other developments deserve your attention.
Amazon’s Bee grows a hive: Bee Frontier and Bee Eclipse
Amazon’s personal-AI wearable startup Bee — acquired by the retail giant last year — announced its first new products since the acquisition. The Bee Frontier ($74.99) is the next generation of the wearable that clips to your clothes or straps to your wrist; the Bee Eclipse ($99.99) is a credit-card-sized recorder with a magnetic back that attaches to your smartphone. Both lean on AI to summarize conversations, generate to-dos, and surface insights — turning a chat with friends into a calendar invite, a lecture into study notes, a doctor’s appointment into a care plan.
The devices run on a “private computing” architecture: raw audio is processed in real time and deleted, and transcripts are encrypted with device-controlled keys that even Amazon employees can’t read. Free users get conversation summaries and 14 days of memory; the $11.99/month Bee Pro tier unlocks unlimited summaries, Alexa+ integration, Amazon.com shopping actions, and third-party app connections (Gmail, Google Calendar, Outlook, Apple HealthKit). The Frontier offers IP67 water resistance, up to seven days of battery life, dual noise-filtering mics, and USB-C. The positioning is unmistakable: Bee is taking direct aim at Plaud and Pocket in the AI-recorder market, at roughly half the price.
Mistral shrinks forecasting: Timestral, 209M parameters, world-beating
French lab Mistral released Timestral, its first family of time-series foundation models — and the results are a masterclass in efficiency. The largest model is just 209M parameters, yet it ranks first on all three of the field’s main public benchmarks — GIFT-Eval, TIME, and fev-bench — beating the previous state of the art while using only two-thirds of the parameters, and outperforming far larger models like TimesFM-3 and Falcon-2.0 on key leaderboards. The family spans four sizes (5M to 209M), and every model sits on the Pareto frontier of accuracy versus size: for each size, no public model forecasts better.
The tech is interesting in its own right: decoupled horizon forecasting (which keeps full history in context while forecast tokens read it), covariate-aware attention (so holiday calendars and weather forecasts can condition predictions without leaking future target values), and a synthetic-first training recipe. But the practical point is the strongest: Timestral needs no GPU at inference — a standard 8-thread server CPU forecasts a day ahead from three weeks of 15-minute data in 10ms (5M model) to 140ms (209M model). For industrial maintenance, energy, supply chains, and finance, that’s a genuinely useful tool that runs anywhere, including air-gapped environments, with fine-tuning available through Mistral Forge. Mistral also announced a new German hub in Munich, doubling down on its “sovereign AI” positioning in Europe’s largest economy.
Google claims a quantum breakthrough
On Google’s official blog, the company said it has “broken open a bottleneck in quantum computing” — a characteristically high-stakes claim from the same lab that announced quantum error-correction milestones in recent years. Details remain thin and the paper has yet to be independently verified, but the framing suggests progress in error correction or qubit coherence, the two problems that have kept quantum computing in the “ten years away” category for a decade. Watch this one closely: Google’s quantum team has a habit of making bold claims and then delivering them.
Security Check: Rogue Agents, Export Curbs, and AI Transparency
The week also delivered a reminder that the AI era’s biggest risks are operational. In India, the government disclosed that rogue AI agents broke into live systems of Indian companies — a warning that resonates far beyond one country: as agentic AI spreads, so does the attack surface, and the security industry is still figuring out how to defend networks from autonomous, adaptive adversaries. Expect “agent-native security” to become a major category in 2027.
On the geopolitical front, Bloomberg reported that Taiwan will curb AI chip exports to China as part of a US trade deal — a significant escalation in the already-frozen semiconductor relationship between the two sides, and a reminder that AI capability is now a first-order instrument of statecraft. Taiwan’s foundries manufacture essentially all of the world’s most advanced AI accelerators; export controls on that supply chain move markets, and they moved this week.
And in the most encouraging transparency story of the week: Anthropic has given METR — the independent nonprofit that evaluates frontier model risks — employee-level access to its systems, and has explicitly given up the right to block METR’s published assessments of Anthropic’s risks, incidents, and practices. For an industry that talks constantly about safety but rarely opens its doors, that is a meaningful precedent. As one observer put it: if you believe in evaluating frontier labs like you’d audit a nuclear plant, this is what the first inspection looks like.
What It Means: The Desktop Is a Platform Again
Step back from the benchmarks and the press releases, and the week’s news tells a coherent story: AI is coming home. For the last three years, the frontier has lived exclusively in the cloud — behind APIs, inside data centers, subject to the pricing and policy whims of a handful of providers. Muse Spark Open is the strongest signal yet that the pendulum is swinging back. A frontier-scale, open-weight, natively multimodal model can now run on hardware that fits on a desk, with a terabyte of unified memory and a 1.2 TB/s memory bus doing the work that used to require a room full of GPUs.
That has three consequences worth thinking about:
- Privacy becomes a feature, not a compromise. When the model runs locally, your prompts, your code, your medical records, and your strategy documents never touch a third-party server. For regulated industries, that’s the difference between “AI we can use” and “AI we can’t touch.”
- The economics invert. The API era charges you per token forever; the local era charges you once. The $38,000 Mac cluster is expensive today — and it will be dramatically cheaper in eighteen months, as it always has been for pro hardware. Organizations that do the math now will be positioned to own their inference infrastructure before the rest of the market catches on.
- The open-weight race just got a lot more interesting. Meta has thrown down the gauntlet against GLM, Kimi, DeepSeek, and Qwen. Apple has picked a side in that war. And in doing so, they’ve turned the “personal supercomputer” from a marketing phrase into an actual category with a reference hardware platform and a flagship model.
None of this is without risk. Open weights mean the model can be used by anyone, for anything — including things the safety frameworks were designed to prevent. The $38,000 price tag means the “personal” AI revolution is, for now, a professional one. And the Apple-Meta alliance is a business relationship, not a friendship; both companies will keep competing everywhere else, and this partnership could fray as easily as it formed.
But the direction of travel is unmistakable. On October 15, 2026, the most powerful open AI model in the United States became something you can hold in a data center of one: your desk. The question for the rest of the industry is no longer whether frontier AI goes local — it’s who else will follow Meta and Apple through that door.
Vito Ruocco covers artificial intelligence and emerging technology. Sources: Meta AI research blog (research.meta.ai), CNBC, TechCrunch, Engadget, The Verge, Bloomberg, Reuters, Mistral AI, and Google’s official blog. All quotes and specifications are drawn from official announcements and reporting published on October 15–16, 2026.